
InfiniBand XDR link on selected Blackwell systems.
NETWORKING & STORAGE FOR AI
Keep every GPU in sync with your data.
Distributed training depends on more than fast accelerators. Plan dedicated InfiniBand, NVMe, and shared storage as one data path for your GPU cluster.
NETWORK, STORAGE, AND TRANSFER, PLANNED TOGETHER
Aggregate read throughput per pod with dedicated WEKA.
Egress included per node, per month.
Local NVMe on selected HGX nodes.
FOLLOW THE DATA
A clear path from workload to checkpoint.
Keep compute, cluster fabric, and storage under one configuration plan. The right path depends on the shape of the job, its parallelism, and how it saves data.
01 COMPUTE
Dedicated GPU nodes
Choose node or rack-scale capacity for your model, memory needs, and training or inference workload.
02 INTERCONNECT
InfiniBand for the cluster
Connect GPUs with dedicated high-speed fabric designed around communication between nodes.
03 DATA
Storage for each stage
Match local NVMe, parallel file storage, and S3-compatible object storage to datasets and checkpoints.
TENSORBAY AIFACTORY01 / 03
COMPUTE
Dedicated GPU nodes04Networking and storage
Your GPUs. Working as one.
Bring compute, data, and storage together in infrastructure dedicated to your model, from the first training batch to the final checkpoint.
Plan my clusterDedicated networking
A network built for your GPUs.
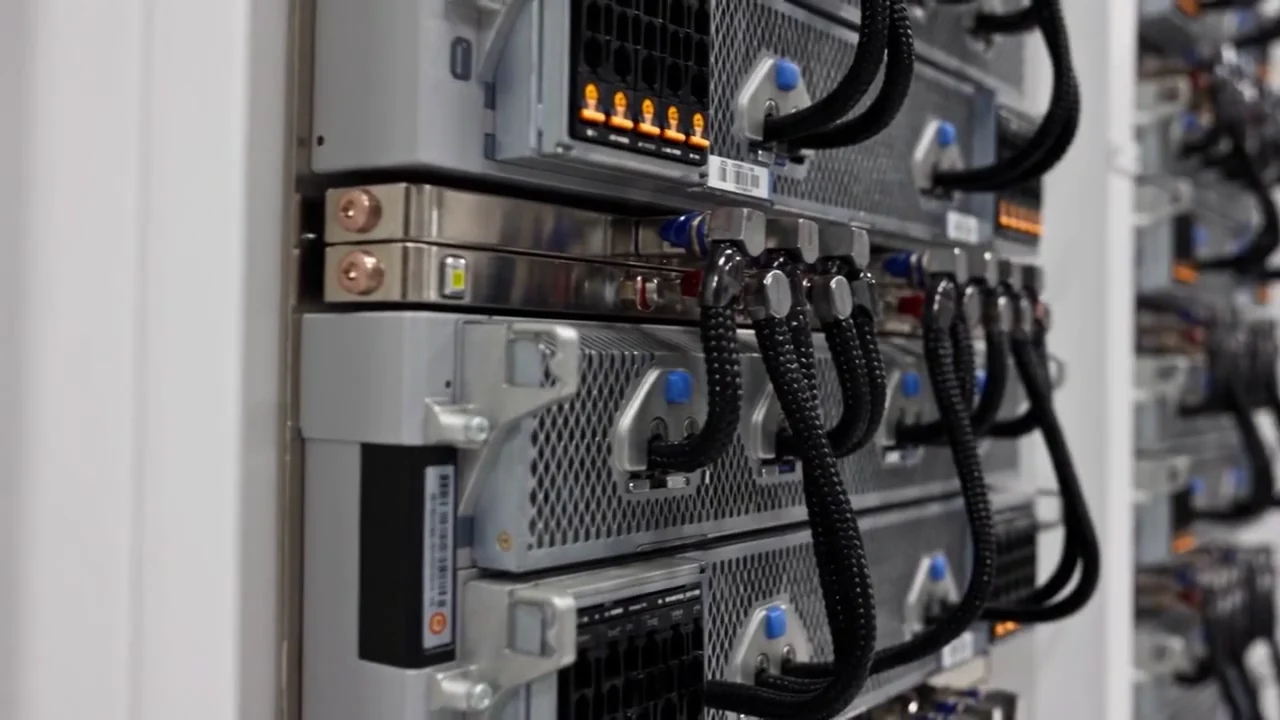
Dedicated InfiniBand connects your cluster with bandwidth for distributed training and data exchange between GPUs.
800Gb/s
per InfiniBand XDR link, Quantum-X800 for Blackwell

Network specifications
- Training fabric — Hopper
- 8×400 Gb/s InfiniBand NDR per node (3.2 Tbps), rail-optimized non-blocking fat-tree, SHARP in-network reduction
- Training fabric — Blackwell
- Quantum-X800 InfiniBand XDR, 800G per link; GB200 racks add a 72-GPU coherent NVLink 5 domain at 1.8 TB/s per GPU
- Oversubscription
- 1:1, all tiers. No blended east-west fabric, no shared spine with other tenants
- Front-end network
- Dual 100 GbE per node, DDoS-protected, BYO-IP supported
Storage
Keep your data in stride.
Local NVMe, WEKA, and S3-compatible storage to load datasets and save checkpoints at the scale your project needs.
Up to
720GB/s
aggregate read throughput per pod, with dedicated WEKA
Storage specifications
- Local scratch
- 30 TB NVMe Gen5 per node, ~55 GB/s read — checkpoint staging without touching the network
- Parallel filesystem
- Managed WEKA, dedicated per cluster: up to 720 GB/s aggregate read per pod, POSIX + GPUDirect Storage
- Object storage
- S3-compatible, NVMe-cached, co-located with compute — $0.055/GB-month hot tier
Data transfer
Take your data further.
Free ingress and traffic between nodes, with an included egress allowance to help you plan your operation.
20TB
egress included per node, per month
Data transfer terms
- Data transfer
- Ingress $0 · 20 TB/node-month egress included, then $1.25/TB · inter-node $0. Free 100G Direct Connect on yearly reservations
TESTED BEFORE HANDOVER
Start with a cluster you can trust.
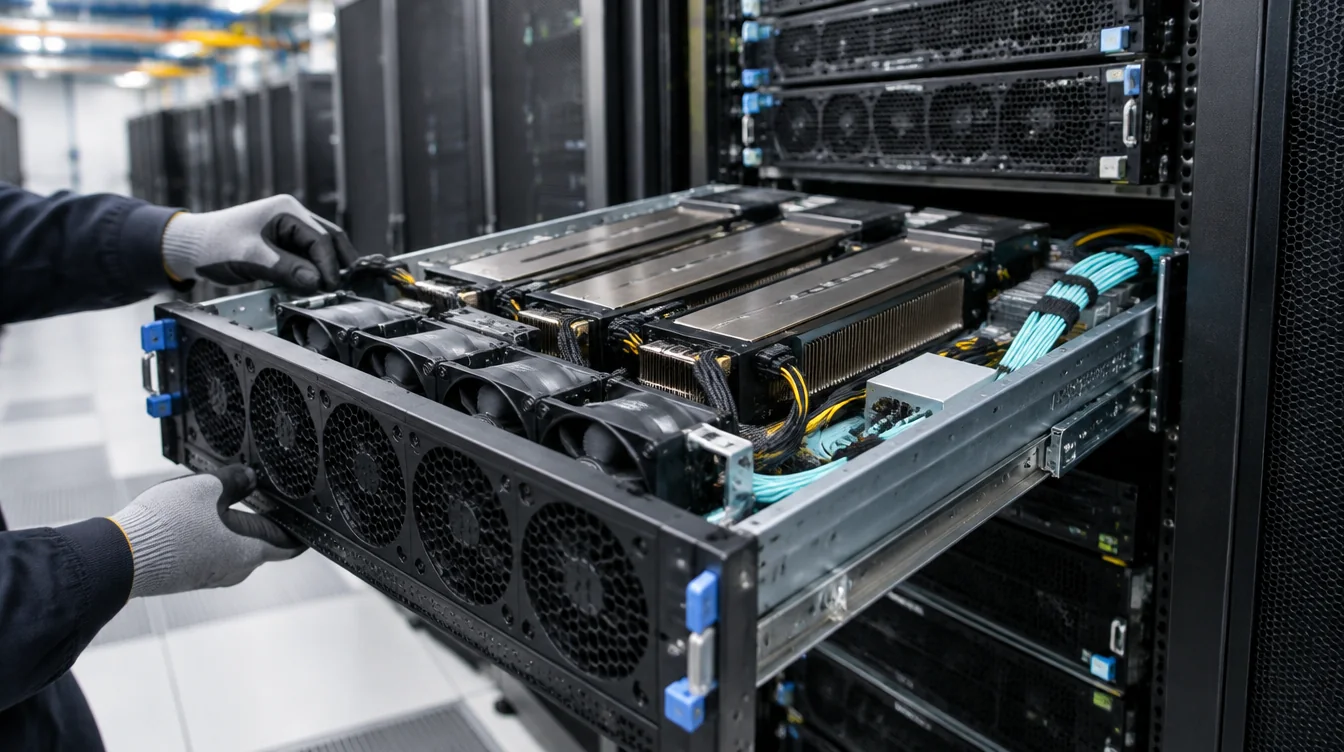
Every cluster goes through 72 hours of load, memory, network, and thermal tests. Your team reviews the results before approving delivery.
72h
ACCEPTANCE TESTING
Load · memory · network · thermal checks
AI WORKLOADS
- TENSORBAY AIFACTORYModel trainingDedicated GPUs and high-speed networking for long training runs.
- TENSORBAY AIFACTORYFine-tuning & research8-GPU nodes for adapting models and iterating on experiments.
- TENSORBAY AIFACTORYProduction inferenceMemory-rich systems for serving models on dedicated infrastructure.
NEVER BUILD ALONE
People who know the stack, within reach.
Bring your model, capacity goals, and timeline. TensorBay’s team can help shape the configuration and next steps.
Talk to sales
- 01A configuration built around your project
- 02A proposal with a delivery timeline
- 03Acceptance testing before you start
05Invest in your next move
Compute to grow. Clarity to invest.
Choose your reservation term, compare capacity, and plan your investment. Here, the conversation starts with open pricing.
| GPU and memory | Monthly termCapacity reserved on a monthly term | Yearly termLower hourly rate |
|---|---|---|
NVIDIAHGX B300288 GB HBM3e per GPU | Monthly from Quote monthlyUS$ 83.20/h | Yearly from Quote yearlyUS$ 58.50/h |
NVIDIAHGX B200180 GB HBM3e per GPU | Monthly from Quote monthlyUS$ 72.80/h | Yearly from Quote yearlyUS$ 50.70/h |
NVIDIAHGX H200141 GB HBM3e per GPU | Monthly from Quote monthlyUS$ 44.20/h | Yearly from Quote yearlyUS$ 31.20/h |
NVIDIAHGX H10080 GB HBM3 per GPU | Monthly from Quote monthlyUS$ 28.60/h | Yearly from Quote yearlyUS$ 19.50/h |
The hourly rate covers the complete 8-GPU node. Choose a term to request your quote.
- SLA
- 99.9% monthly + 15-min node replacement + goodput credits
- Scale
- 128–10,000+ GPUs · dedicated fabric per tenant
- Billing
- Per-minute metering inside the reservation · $0 ingress
Every detail accounted for
Your infrastructure. No blind spots.
See what is included and explore rates for storage, data transfer, and networking.
Talk to a specialistStorage
- Local NVMe scratch — 30 TB per nodeIncluded
- Parallel filesystem — managed WEKAdedicated per cluster$0.09/GB-mo
- Object storage — hot, S3-compatibleNVMe-cached, co-located$0.055/GB-mo
- Object storage — archive$0.015/GB-mo
- Snapshots$0.021/GB-mo
Data transfer
- Ingressalways$0
- Egress included20 TB/node-mo
- Egress overageall sites$1.25/TB
- Inter-node / east-westInfiniBand fabric$0
Networking
- East-west InfiniBand fabricdedicated per clusterIncluded
- Private VLAN / VPCIncluded
- Additional public IPv4IPv6 free$4/IP-mo
- BYO-IP — /24 v4 or /48 v6$200 setupFree
- Managed firewall$4/node-mo
- DDoS protectionIncluded
- Direct Connect 10G / 100G100G free on yearly terms$450 / $1,800-mo
USD prices per 8-GPU HGX node-hour; rack-scale systems are quoted per rack. Taxes excluded. Managed Slurm and Kubernetes control planes are included. Storage and Direct Connect follow the rates above. Ask about long-term contract options.
Get my proposalIs GPU pricing per GPU or per node?
Published HGX prices are in USD per hour for a complete node with 8 GPUs, within a monthly or yearly reservation. NVL72 systems are quoted per rack. Taxes are not included.
Which NVIDIA GPU should I choose for my AI project?
Compare GPU memory, network requirements and your training or inference workload. The hardware section lists H100, H200, B200, B300 and full rack systems. Our team can help size a configuration based on your model, dataset and capacity requirements.
Can I use a dedicated cluster for training, fine-tuning and inference?
Yes. TensorBay offers dedicated NVIDIA GPU infrastructure for model training, fine-tuning and inference. You can work with Slurm, Kubernetes or SSH and configure the software environment for your workload.
What happens after I request a quote?
Share the GPU, capacity and reservation term you need, or describe your project. Our team reviews the requirements and prepares a proposal within 48 hours, including configuration and delivery timing. Capacity and final terms are confirmed in the proposal.
08Give your idea room to grow
Design a data path that keeps your AI work moving.
Tell us about your GPUs, dataset, and training or inference pattern. We will help map the network and storage configuration around the workload.
- A configuration built around your project
- A proposal with a delivery timeline
- Acceptance testing before you start