
Of system checks before cluster handover.
EXPERT SUPPORT, FROM PLAN TO FIRST RUN
Experts beside you, from planning to first run.
Shape your dedicated GPU environment with specialists who understand the compute, networking, storage, and operational checks behind it.
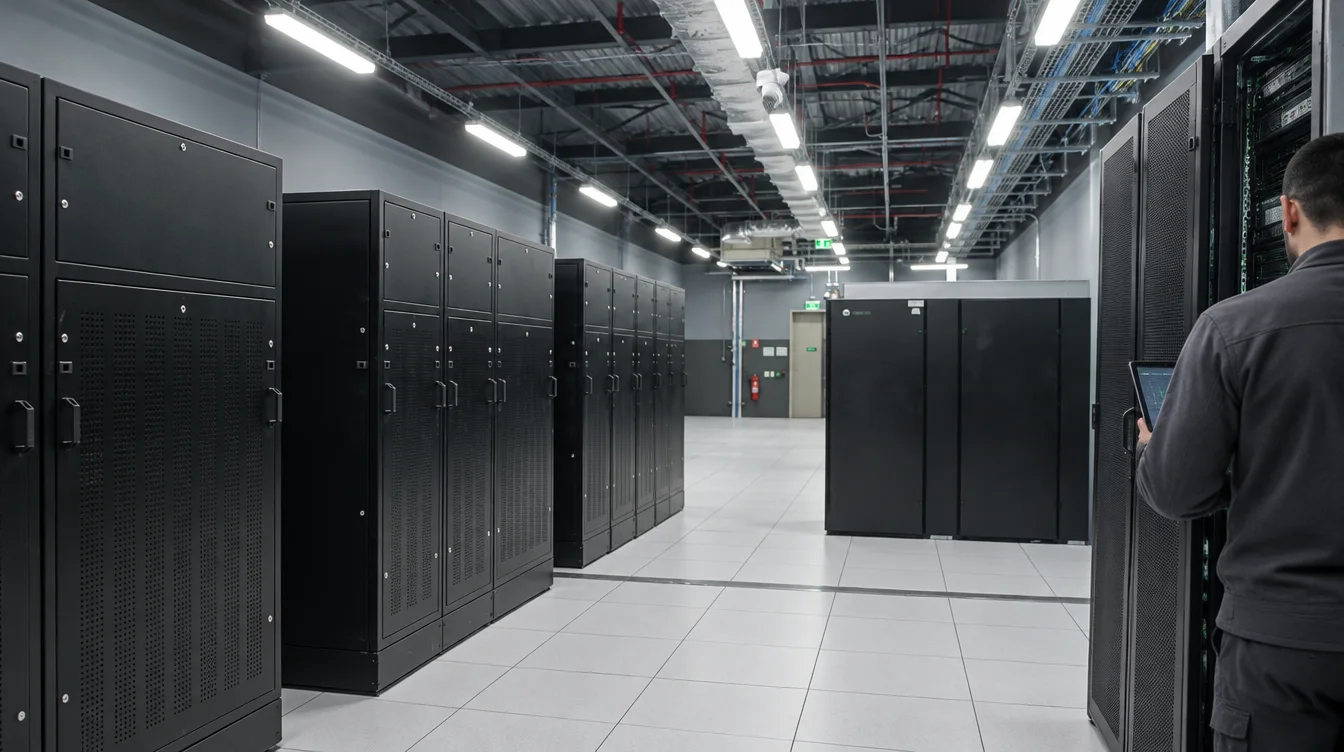
PREPARED BEFORE YOUR TEAM TAKES OVER
Node-replacement service level.
Load, memory, network, and thermal readiness.
A CLEAR OPERATING PATH
A cluster you can understand before it is yours.
Make each technical decision visible, from the first workload conversation to the last readiness check before handover.
01 Scope the workload
Align your model, GPU memory, node count, dataset, network, and timeline.
02 Plan the system
Coordinate compute, data path, reservation terms, and delivery around the job.
03 Review readiness
See load, memory, network, and thermal test results before handover.
SUPPORT THROUGH THE DETAILS
Clarity at every decision point.
Dedicated infrastructure has many moving parts. Keep the decisions connected to your workload and your next milestone.
01
CAPACITY PLANNING
A configuration around the job
Align the model, GPU memory, node count, and run timeline before making a reservation.02
ACCEPTANCE TESTING
Results your team can review
Load, memory, network, and thermal checks are completed before handover, with results ready to review.03
OPERATIONAL CONTINUITY
A path to keep work moving
Eligible configurations include same-rack spare nodes and a 15-minute node-replacement SLA. Confirm the contracted scope with our team.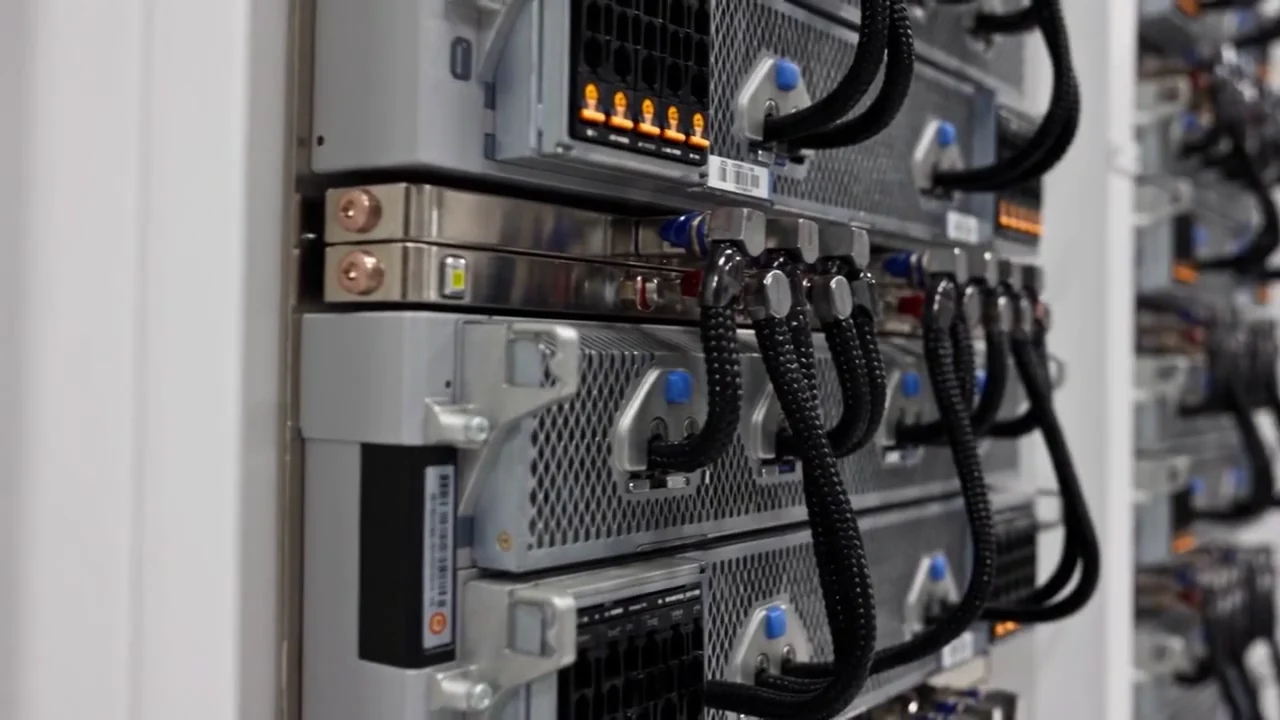
TESTED BEFORE HANDOVER
Start with a cluster you can trust.
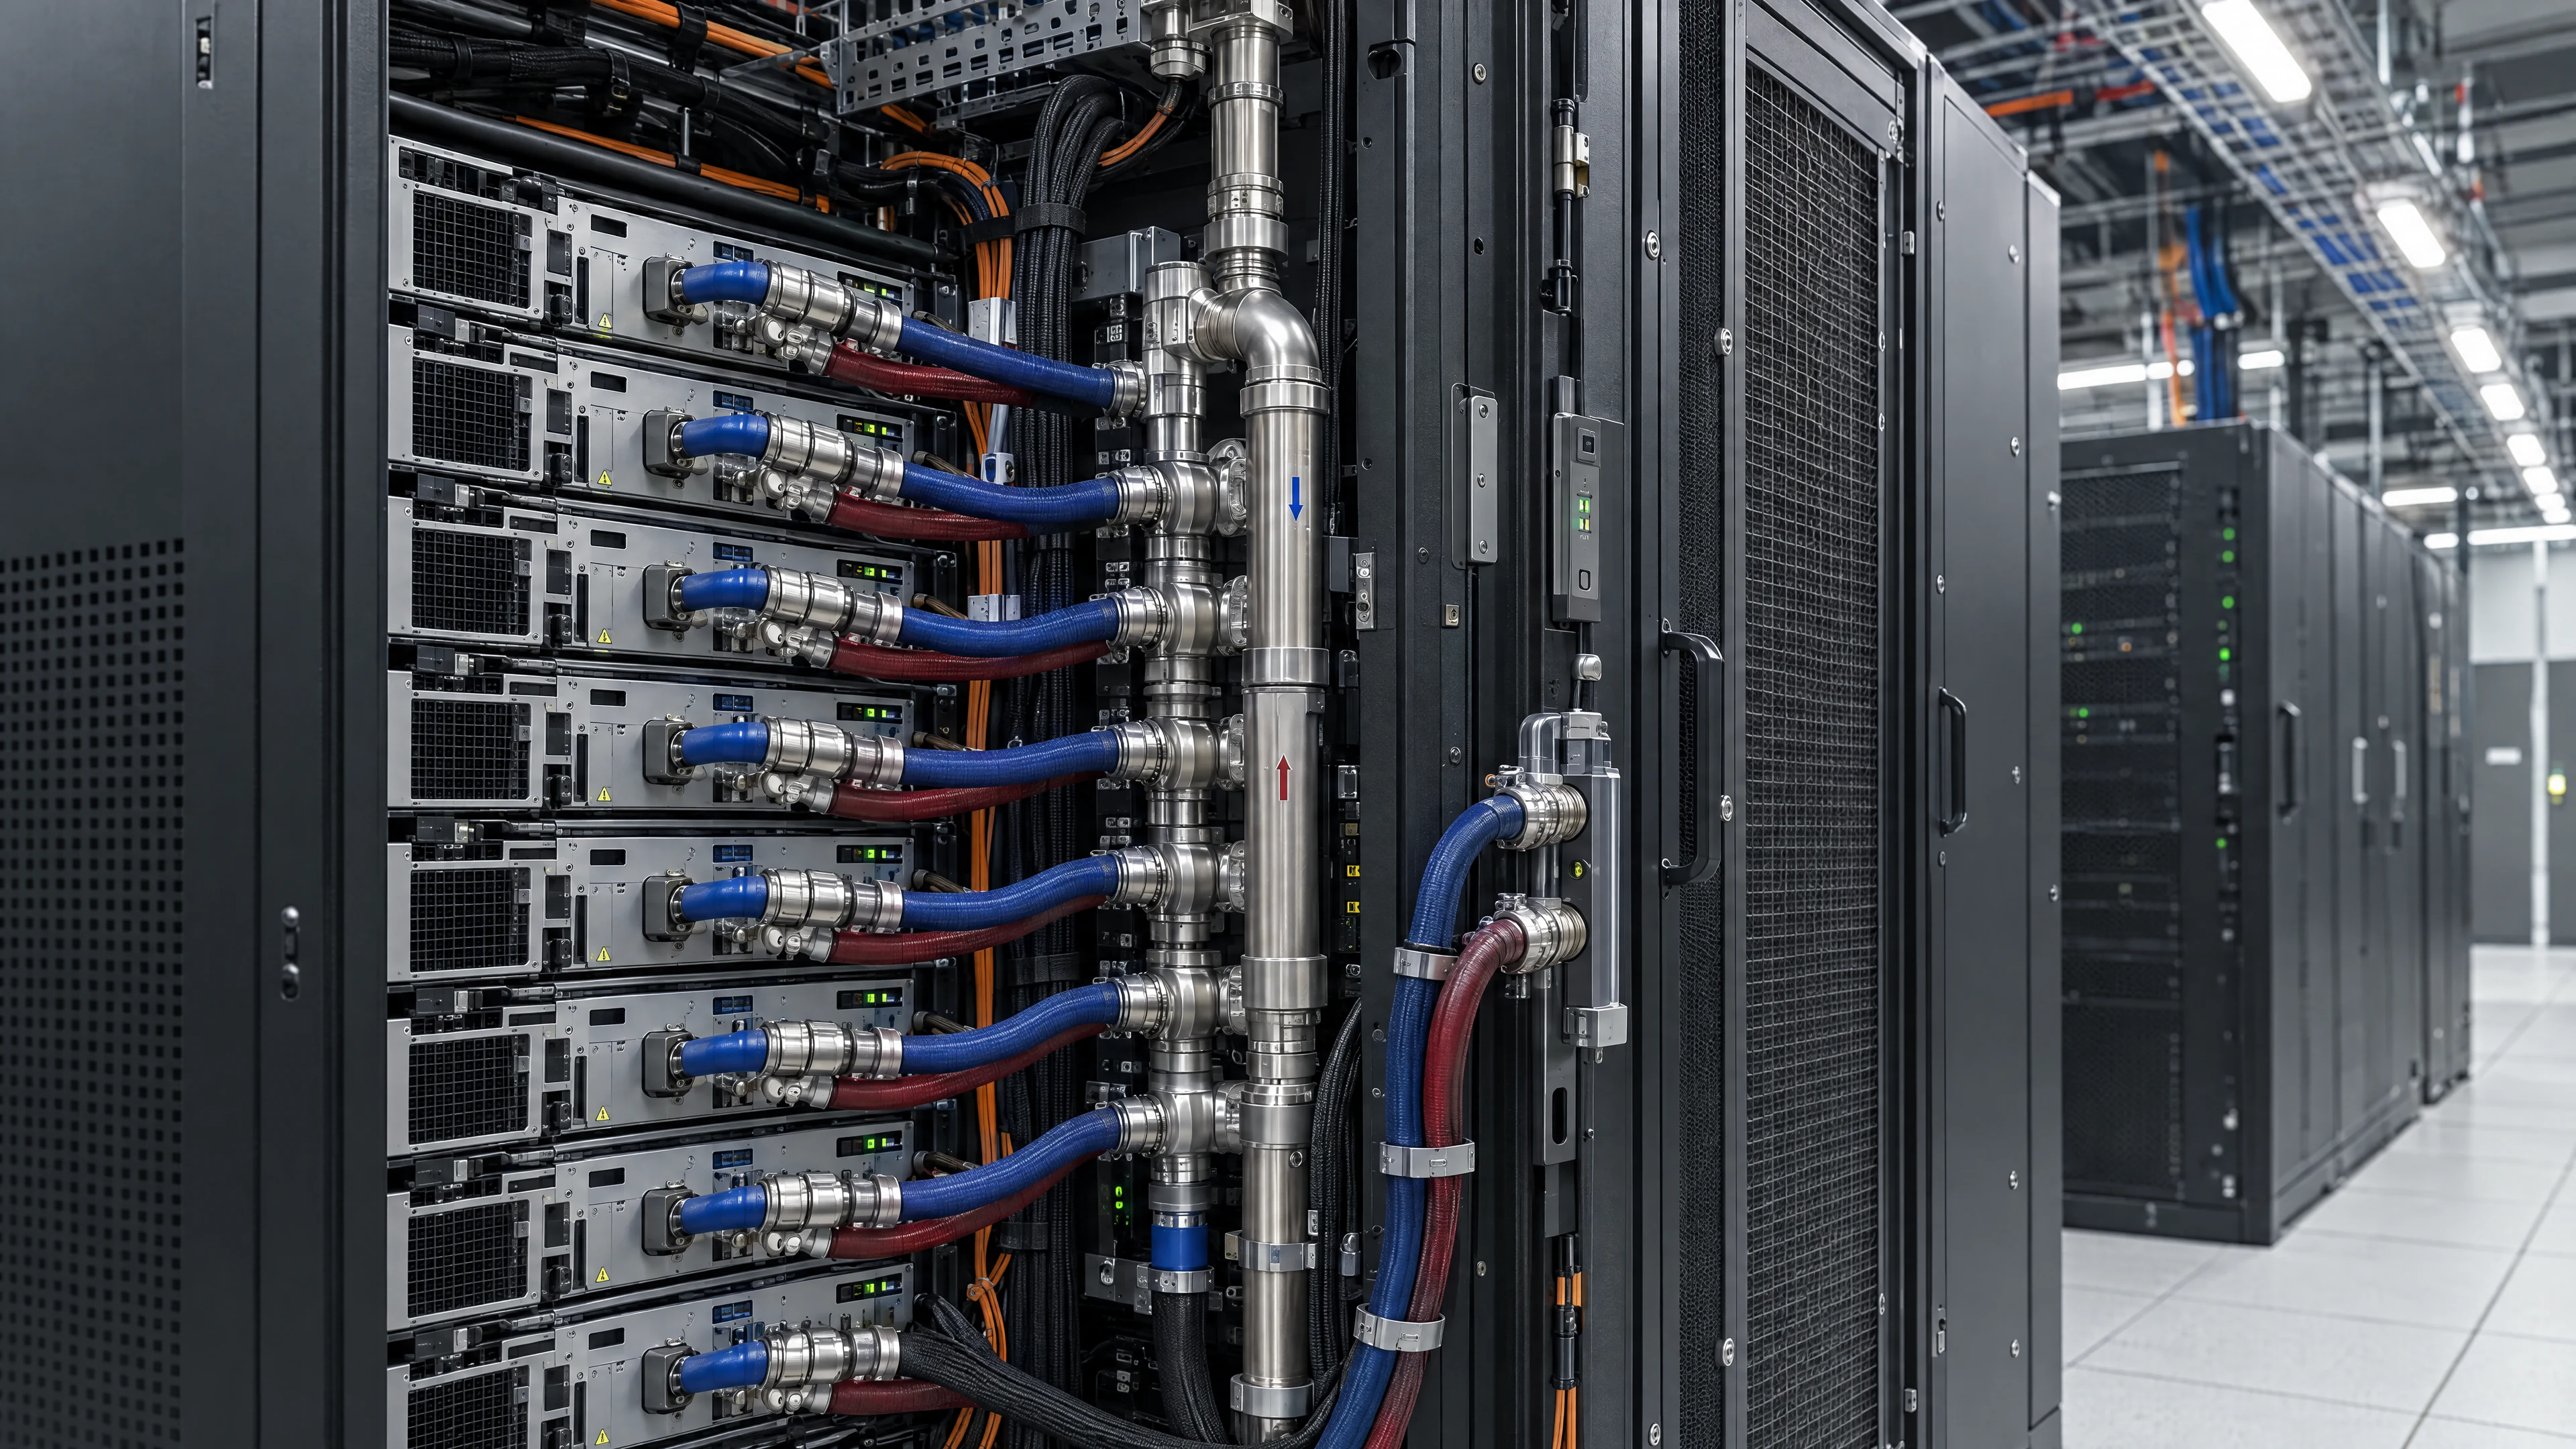
Every cluster goes through 72 hours of load, memory, network, and thermal tests. Your team reviews the results before approving delivery.
72h
ACCEPTANCE TESTING
Load · memory · network · thermal checks
AI WORKLOADS
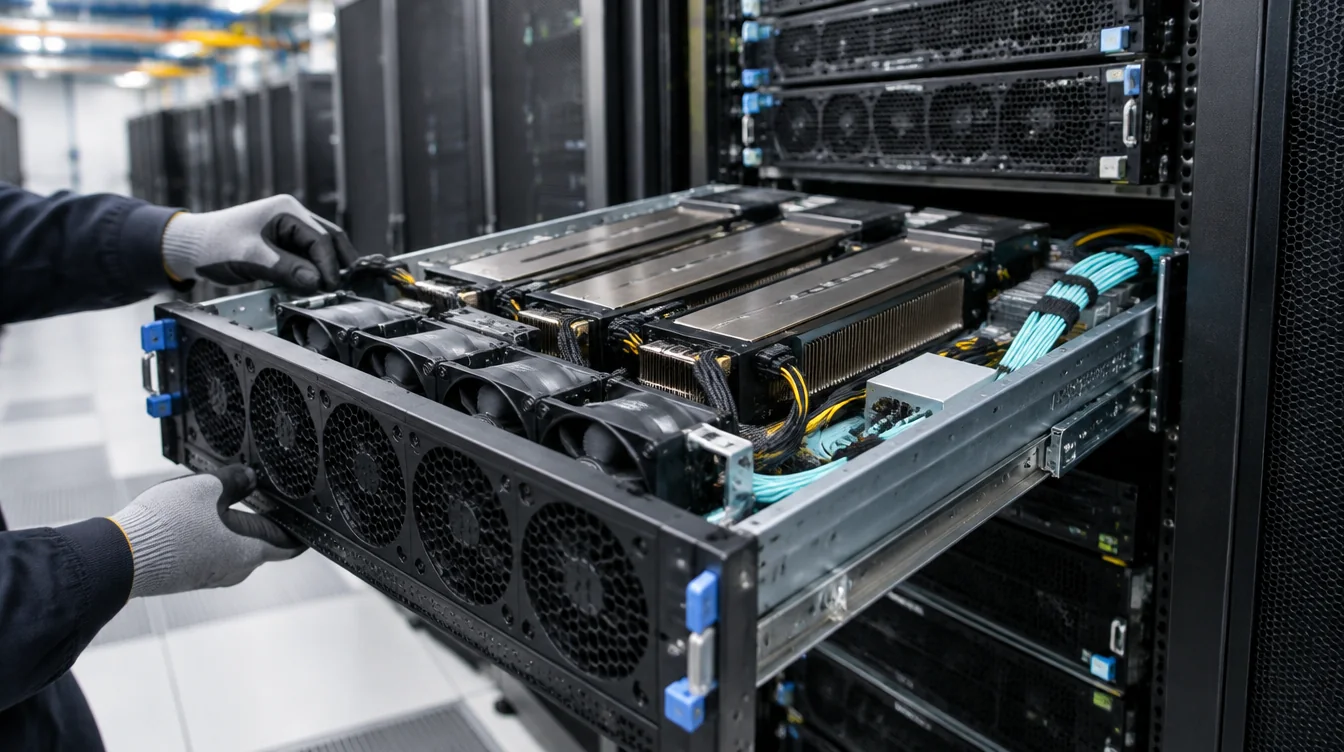
- TENSORBAY AIFACTORYModel trainingDedicated GPUs and high-speed networking for long training runs.
- TENSORBAY AIFACTORYFine-tuning & research8-GPU nodes for adapting models and iterating on experiments.
- TENSORBAY AIFACTORYProduction inferenceMemory-rich systems for serving models on dedicated infrastructure.
Is GPU pricing per GPU or per node?
Published HGX prices are in USD per hour for a complete node with 8 GPUs, within a monthly or yearly reservation. NVL72 systems are quoted per rack. Taxes are not included.
Which NVIDIA GPU should I choose for my AI project?
Compare GPU memory, network requirements and your training or inference workload. The hardware section lists H100, H200, B200, B300 and full rack systems. Our team can help size a configuration based on your model, dataset and capacity requirements.
Can I use a dedicated cluster for training, fine-tuning and inference?
Yes. TensorBay offers dedicated NVIDIA GPU infrastructure for model training, fine-tuning and inference. You can work with Slurm, Kubernetes or SSH and configure the software environment for your workload.
What happens after I request a quote?
Share the GPU, capacity and reservation term you need, or describe your project. Our team reviews the requirements and prepares a proposal within 48 hours, including configuration and delivery timing. Capacity and final terms are confirmed in the proposal.
08Give your idea room to grow
Bring us the model. Leave with a plan.
Tell us about your workload, capacity goals, and timeline. We will help map the configuration and the steps to get it ready.
- A configuration built around your project
- A proposal with a delivery timeline
- Acceptance testing before you start