AI Factory infrastructure
NVIDIA HGX B300
Memory-rich compute for large models and inference
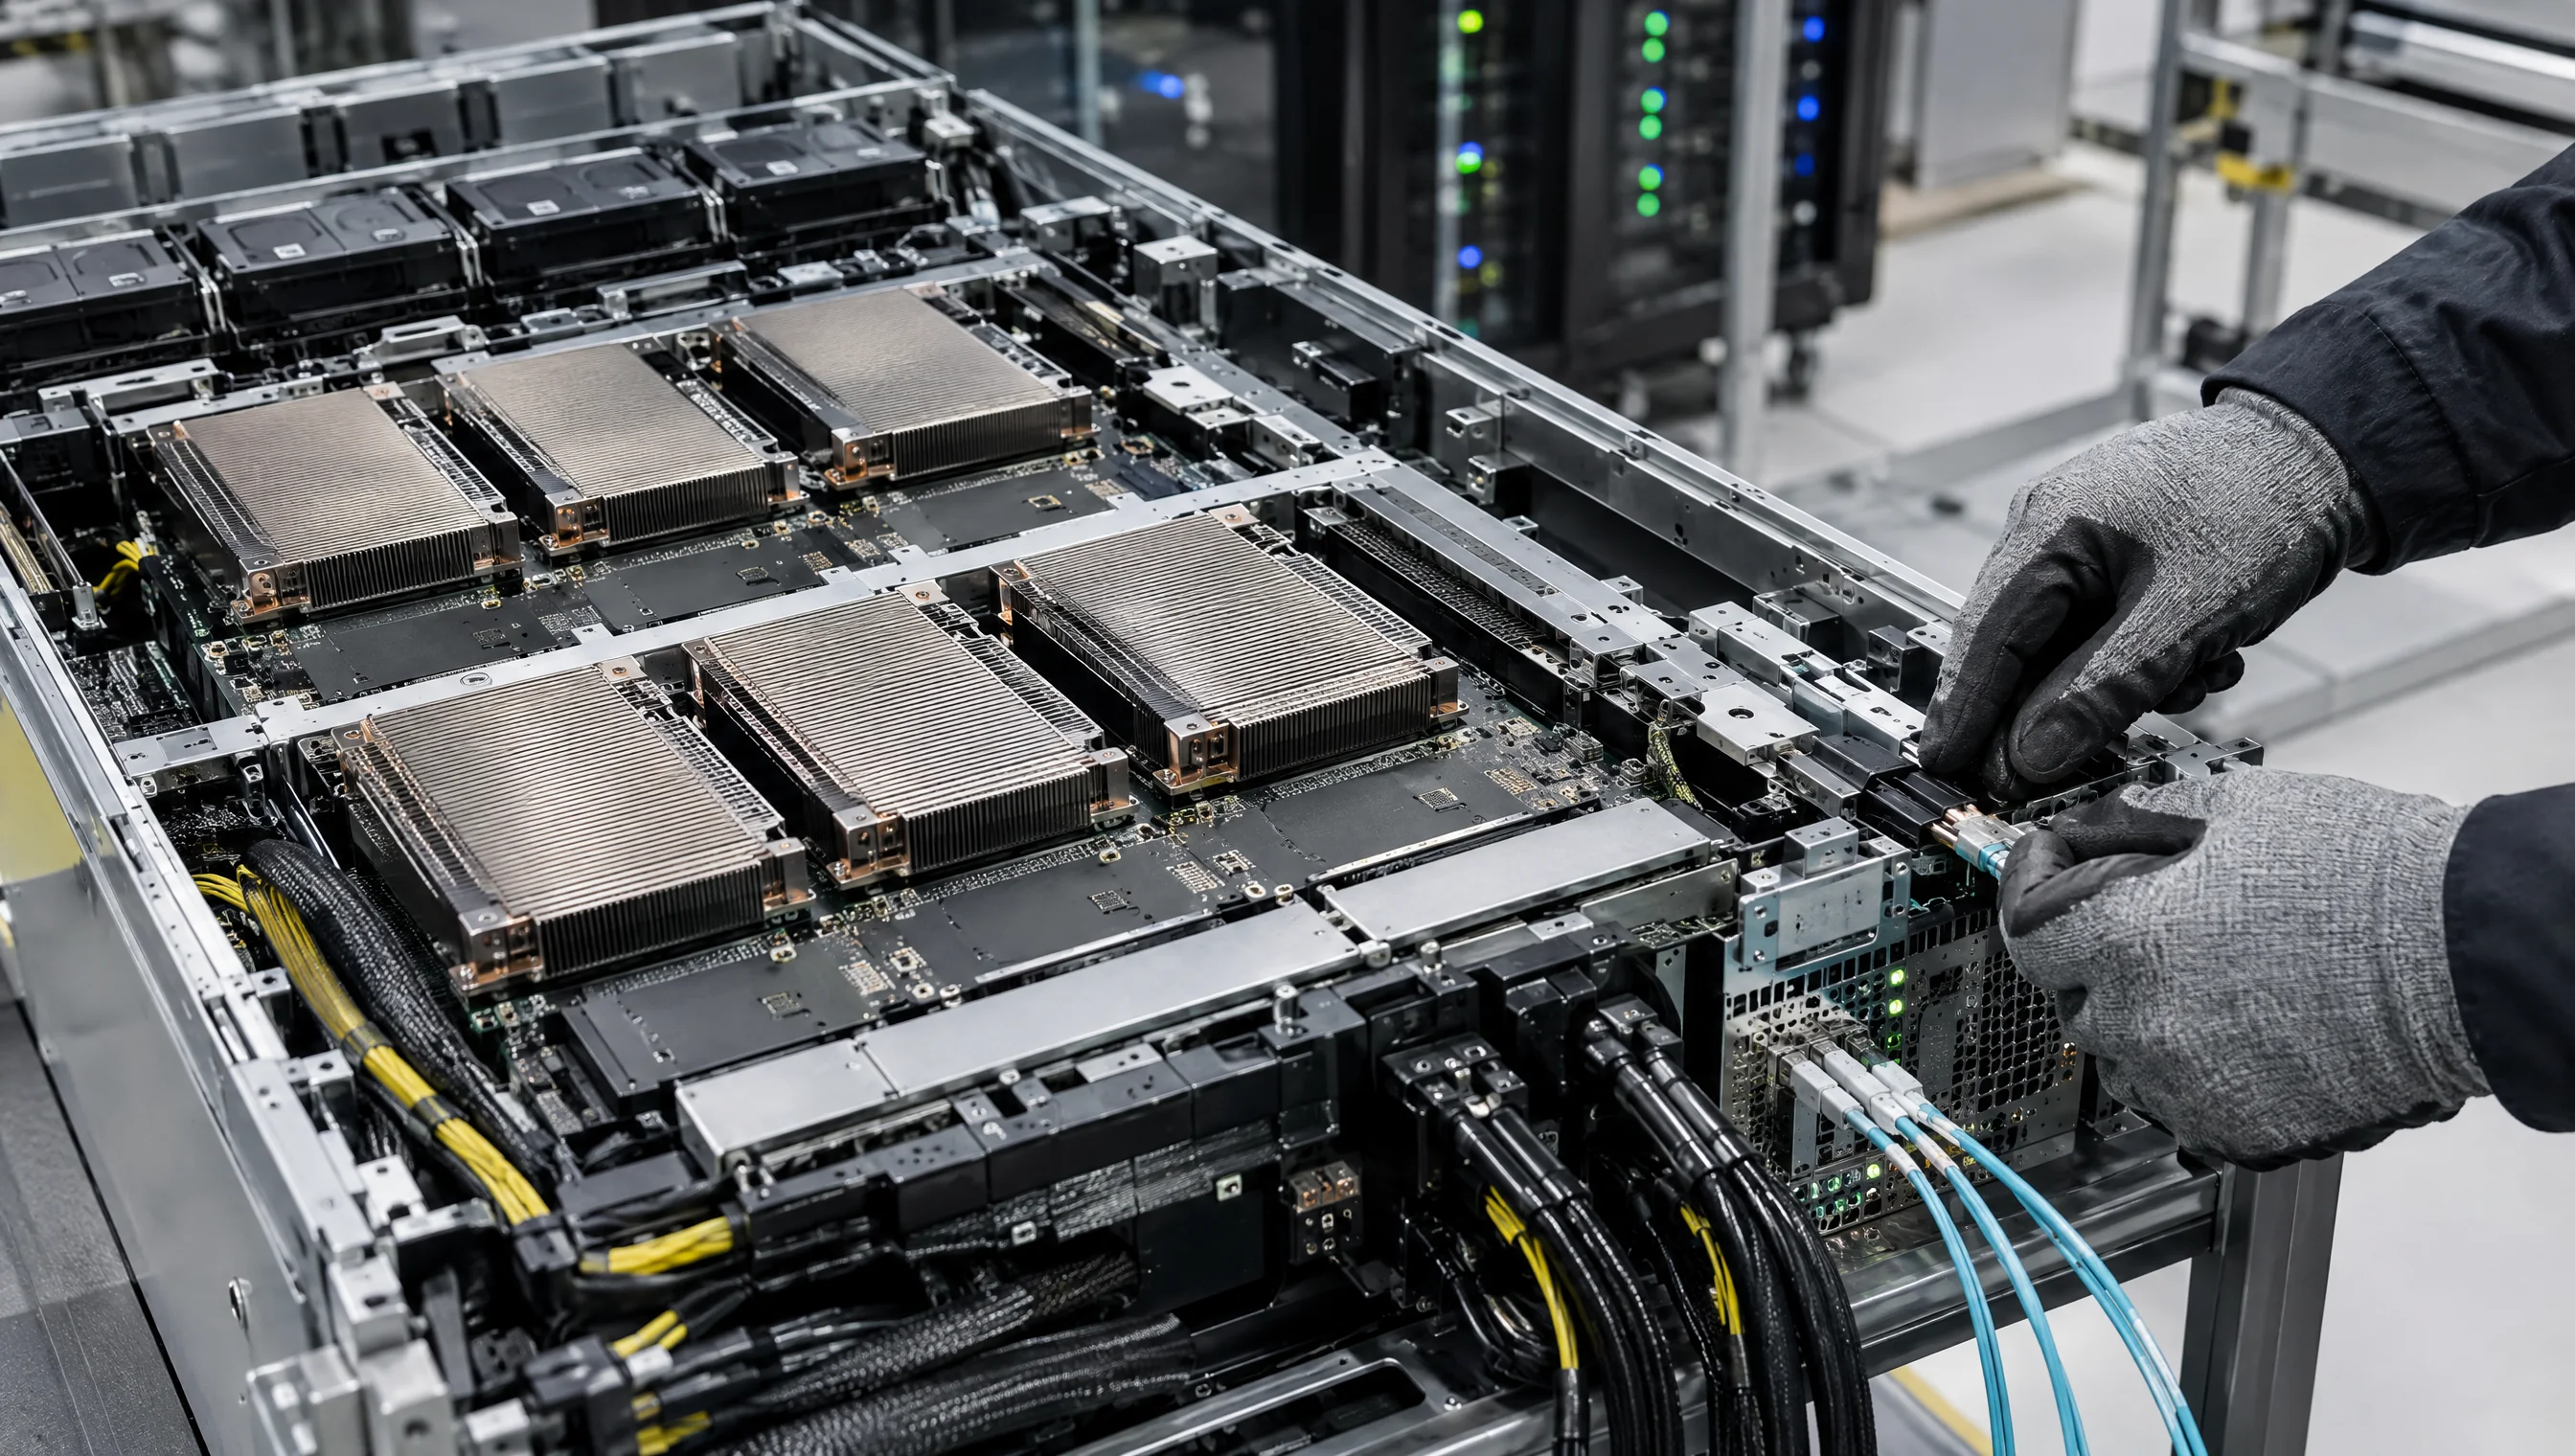
Build your AI infrastructure around NVIDIA HGX B300, with dedicated hardware, high-speed networking and a reservation tailored to your project.
Memory per GPU
288 GB HBM3e- Inside the node
- 8 GPU · 30 TB NVMe · 2 TB RAM
- Node interconnect
- Quantum-X800 XDR 800G
Your dedicated configuration
Inside your HGX B300 cluster
- Memory per GPU
- 288 GB HBM3e · 8 TB/s
- GPU interconnect
- NVLink 5 · 1.8 TB/s per GPU
- Node interconnect
- Quantum-X800 XDR 800G
- Inside the node
- 8 GPU · 30 TB NVMe · 2 TB RAM
HGX B300 pricing and reservations
USD per hour for the complete 8-GPU node
USD prices per 8-GPU HGX node-hour; rack-scale systems are quoted per rack. Taxes excluded. Managed Slurm and Kubernetes control planes are included. Storage and Direct Connect follow the rates above. Ask about long-term contract options.
See all pricingPlan your GPU capacity
Is HGX B300 the right fit for your model?
Start with the constraints of your workload, then compare the configuration and reservation cost.
Evaluate B300 when memory capacity limits your model, context length or batch size. Compare it with B200 using the same model, precision and serving settings before choosing your reservation.
Inference sizing: vLLM optimization guideWhat to include in your quote request
- Model and workload: training, fine-tuning or inference.
- Precision, context length, batch size and concurrent users.
- GPU count, dataset size, storage and network requirements.
- Reservation term, target start date and success criteria.
Compare memory and reservation rates
| GPU | Memory per GPU | Monthly term | Yearly term |
|---|---|---|---|
| HGX B300 | 288 GB HBM3e | from $83.20 | from $58.50 |
| HGX B200 | 180 GB HBM3e | from $72.80 | from $50.70 |
| HGX H200 | 141 GB HBM3e | from $44.20 | from $31.20 |
| HGX H100 | 80 GB HBM3 | from $28.60 | from $19.50 |
Prices are in USD per hour for a complete 8-GPU node. Memory capacity alone does not determine performance. Final capacity, availability and terms are confirmed in your proposal.
Get my proposalIs GPU pricing per GPU or per node?
Published HGX prices are in USD per hour for a complete node with 8 GPUs, within a monthly or yearly reservation. NVL72 systems are quoted per rack. Taxes are not included.
Which NVIDIA GPU should I choose for my AI project?
Compare GPU memory, network requirements and your training or inference workload. The hardware section lists H100, H200, B200, B300 and full rack systems. Our team can help size a configuration based on your model, dataset and capacity requirements.
Can I use a dedicated cluster for training, fine-tuning and inference?
Yes. TensorBay offers dedicated NVIDIA GPU infrastructure for model training, fine-tuning and inference. You can work with Slurm, Kubernetes or SSH and configure the software environment for your workload.
What happens after I request a quote?
Share the GPU, capacity and reservation term you need, or describe your project. Our team reviews the requirements and prepares a proposal within 48 hours, including configuration and delivery timing. Capacity and final terms are confirmed in the proposal.
08Give your idea room to grow
Your next AI breakthrough starts with a conversation.
Bring us your challenge. Our team will help define your GPUs, capacity, and timeline. Get a proposal within 48 hours to launch your project or take it further.
- A configuration built around your project
- A proposal with a delivery timeline
- Acceptance testing before you start