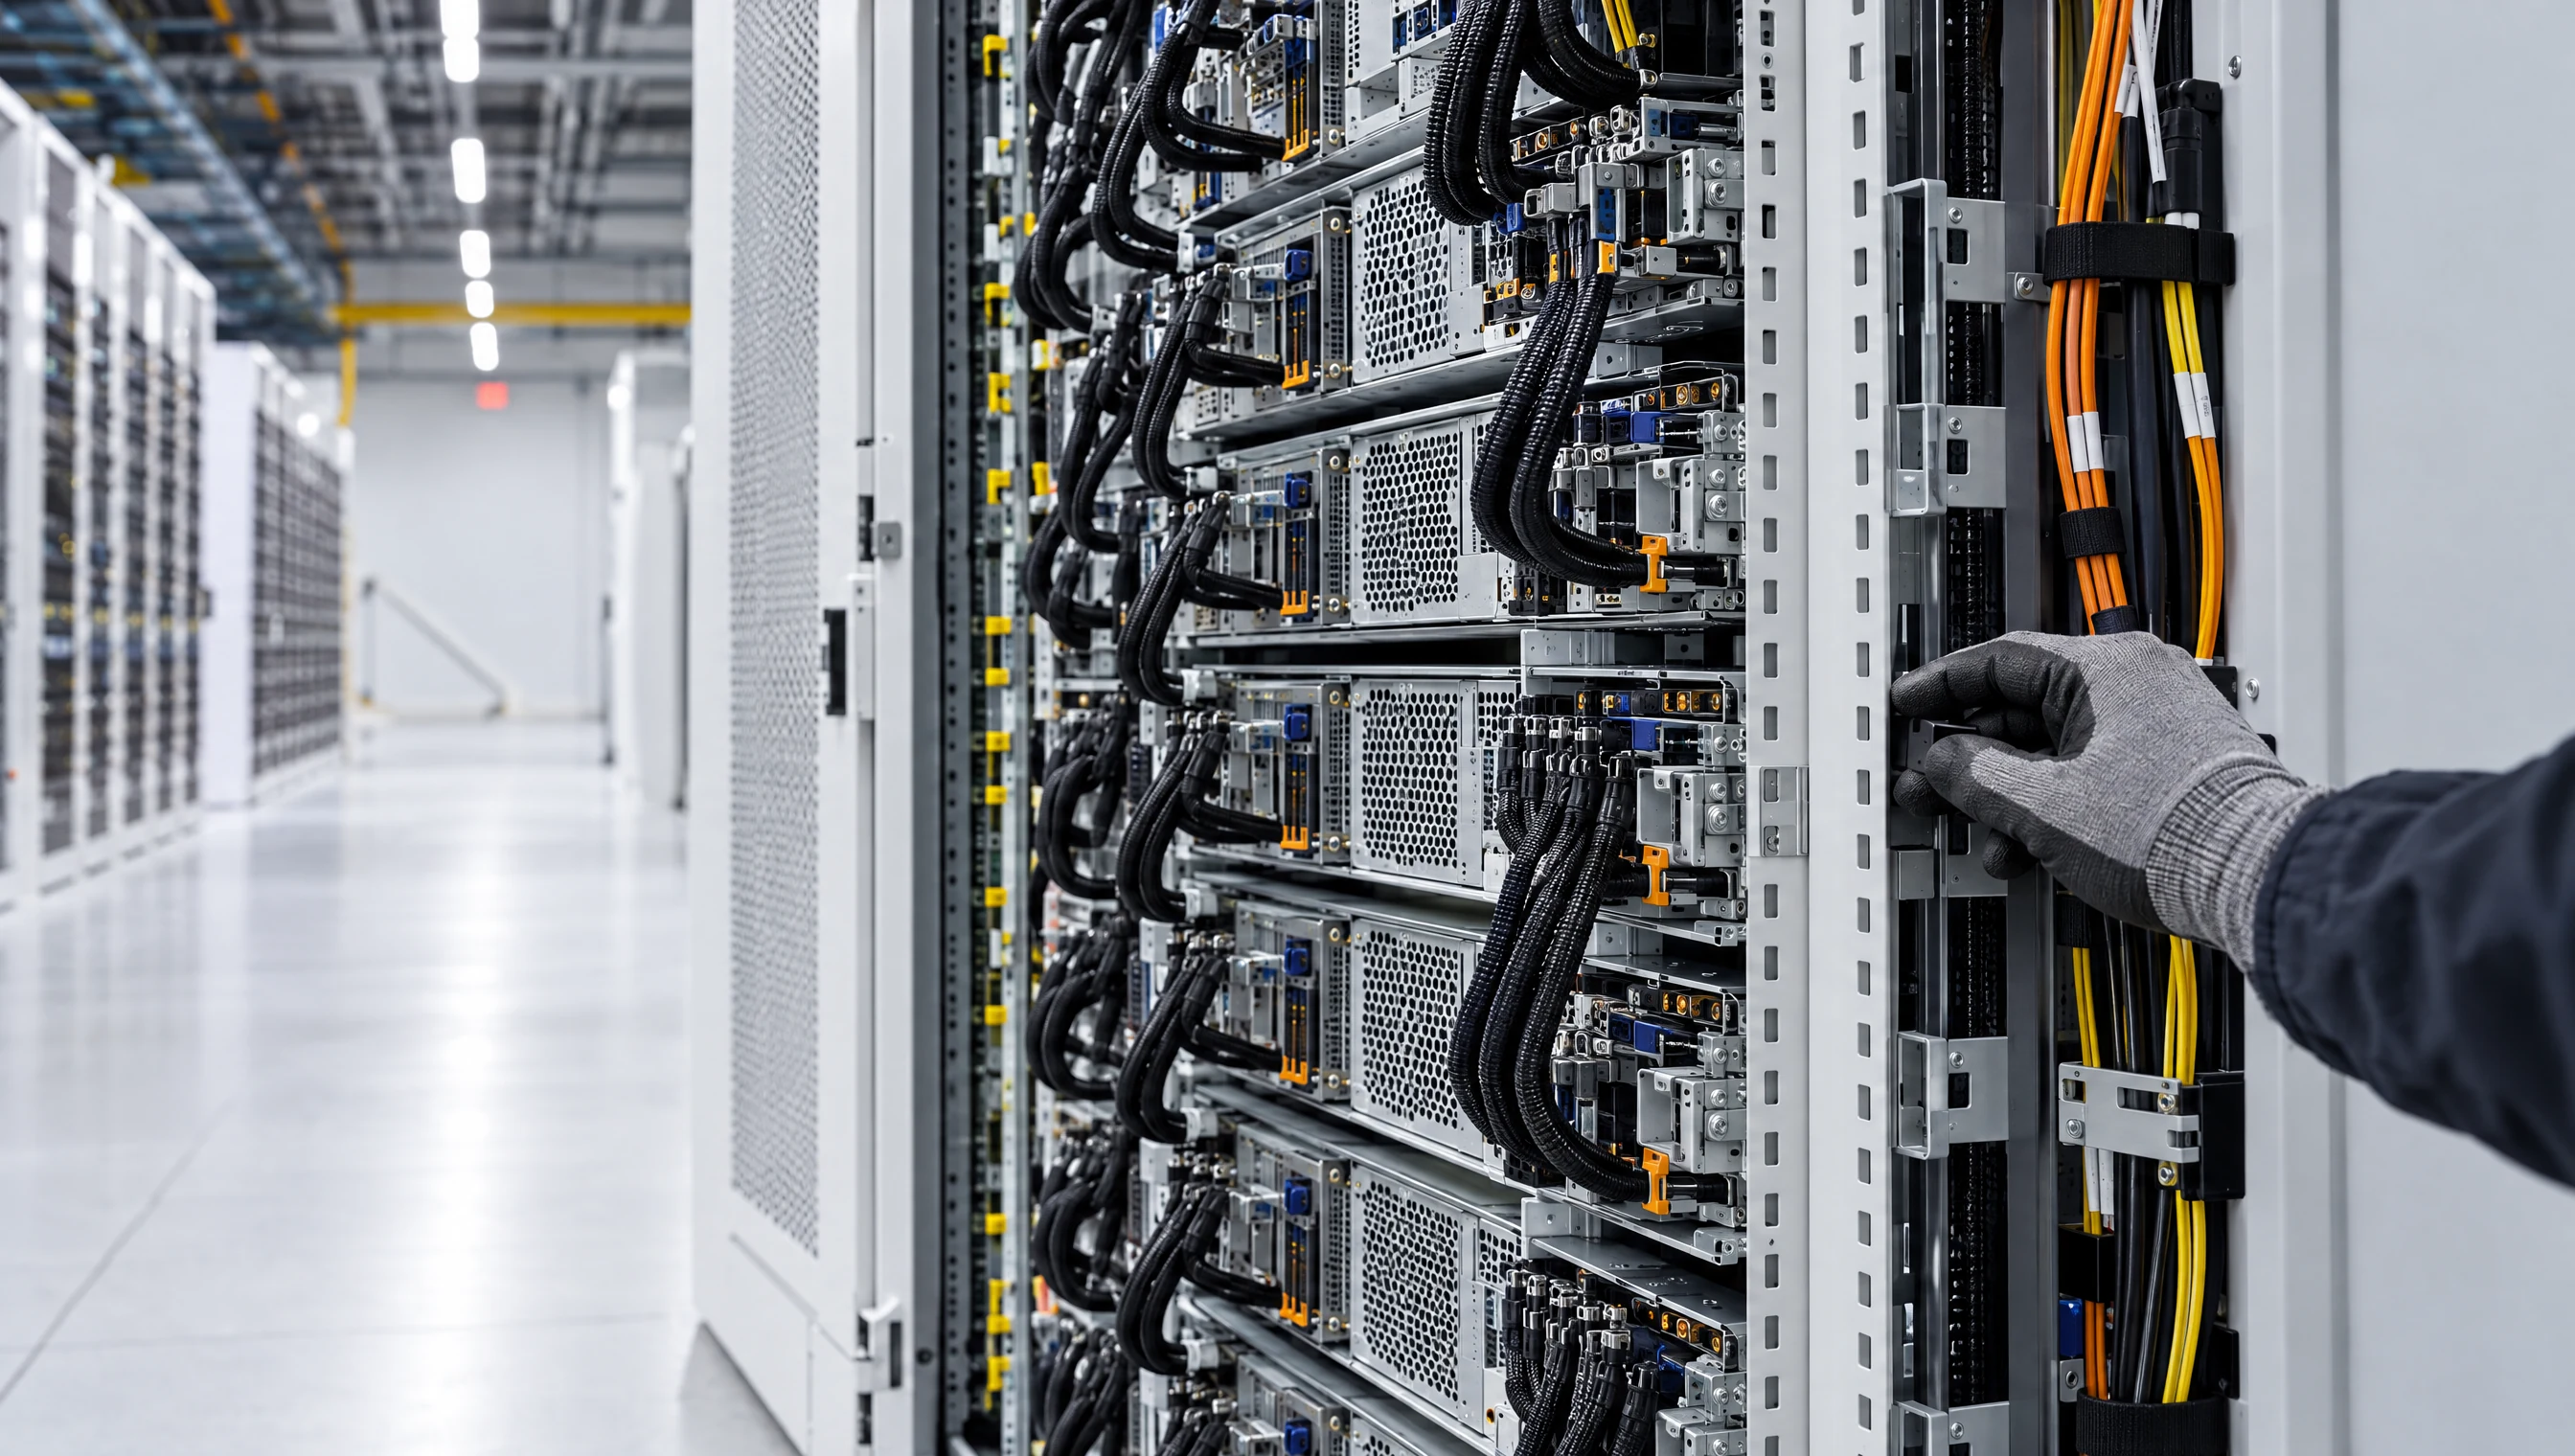
Next-generation spotlight
Early buy — delivery March 2027
VR200 NVL72
Plan your next cycle with the Rubin generation
- Memory per GPU
- 288 GB HBM4
- Inside the node
- NVL72 rack · liquid-cooled
- Node interconnect
- ConnectX-9 · 1.6T XDR
GPU COMPUTE
Run training, fine-tuning, and inference on dedicated systems. Compare 8-GPU nodes and rack-scale configurations with high-speed networking and transparent reservation pricing.
06From research to results
Give your foundation models the capacity they demand. Reserved clusters, dedicated networking, and spare nodes support the infrastructure behind your most ambitious training runs.
Explore B200, GB200, and GB300Adapt models to your data and business challenges. Dedicated 8-GPU nodes and persistent storage give your team room to test, fine-tune, and evolve.
Find your H100 or H200Bring large models to production with memory-rich GPUs. Serve long-context applications on a dedicated infrastructure foundation you can plan around.
Discover H200 and B30001Find your compute
Training, fine-tuning, or inference: every workload has its own demands. Find the capacity that fits your team, your model, and your budget.
See all pricingNext-generation spotlight
Early buy — delivery March 2027
Plan your next cycle with the Rubin generation
Capacity for MoE models and reasoning AI
GPU interconnect72-GPU coherent NVLink 5 domain
Rack-scale
Memory-rich compute for large models and inference
GPU interconnectNVLink 5 · 1.8 TB/s per GPU
Blackwell Ultra
A 72-GPU foundation for your largest models
GPU interconnect72-GPU coherent NVLink 5 domain
Rack-scale
Frontier model training and FP4 inference
GPU interconnectNVLink 5 · 1.8 TB/s per GPU
New — commissioning
More memory for long-context model serving
Training and fine-tuning with your budget in mind
Prices in USD per 8-GPU node-hour. Rack-scale systems are quoted separately. Subject to capacity and contract terms.
TESTED BEFORE HANDOVER
Every cluster goes through 72 hours of load, memory, network, and thermal tests. Your team reviews the results before approving delivery.
Load · memory · network · thermal checks
03Infrastructure behind your ambition
Power, cooling, GPUs, and networking. We design and operate every layer together to give your AI a foundation ready to grow.
PUE 1.12
Direct-to-chip liquid cooling in 130 kW racks. Engineered for the demands of intensive AI workloads.
24,000+ GPUs
Capacity expands in six-week cycles, with readiness checks before each handover.
97.4%
Cluster goodput over the last 90 days: the share of capacity translated into useful work.
04Networking and storage
Bring compute, data, and storage together in infrastructure dedicated to your model, from the first training batch to the final checkpoint.
Plan my clusterDedicated networking
Dedicated InfiniBand connects your cluster with bandwidth for distributed training and data exchange between GPUs.
800Gb/s
per InfiniBand XDR link, Quantum-X800 for Blackwell
Storage
Local NVMe, WEKA, and S3-compatible storage to load datasets and save checkpoints at the scale your project needs.
720GB/s
aggregate read throughput per pod, with dedicated WEKA
Data transfer
Free ingress and traffic between nodes, with an included egress allowance to help you plan your operation.
20TB
egress included per node, per month
EXPLORE TENSORBAY
Explore the GPU systems, infrastructure, and pricing that can move your AI project forward.
EARLY RESERVATIONS
Review the Vera Rubin rack-scale configuration and its early reservation timeline.
NVIDIA VR200 NVL72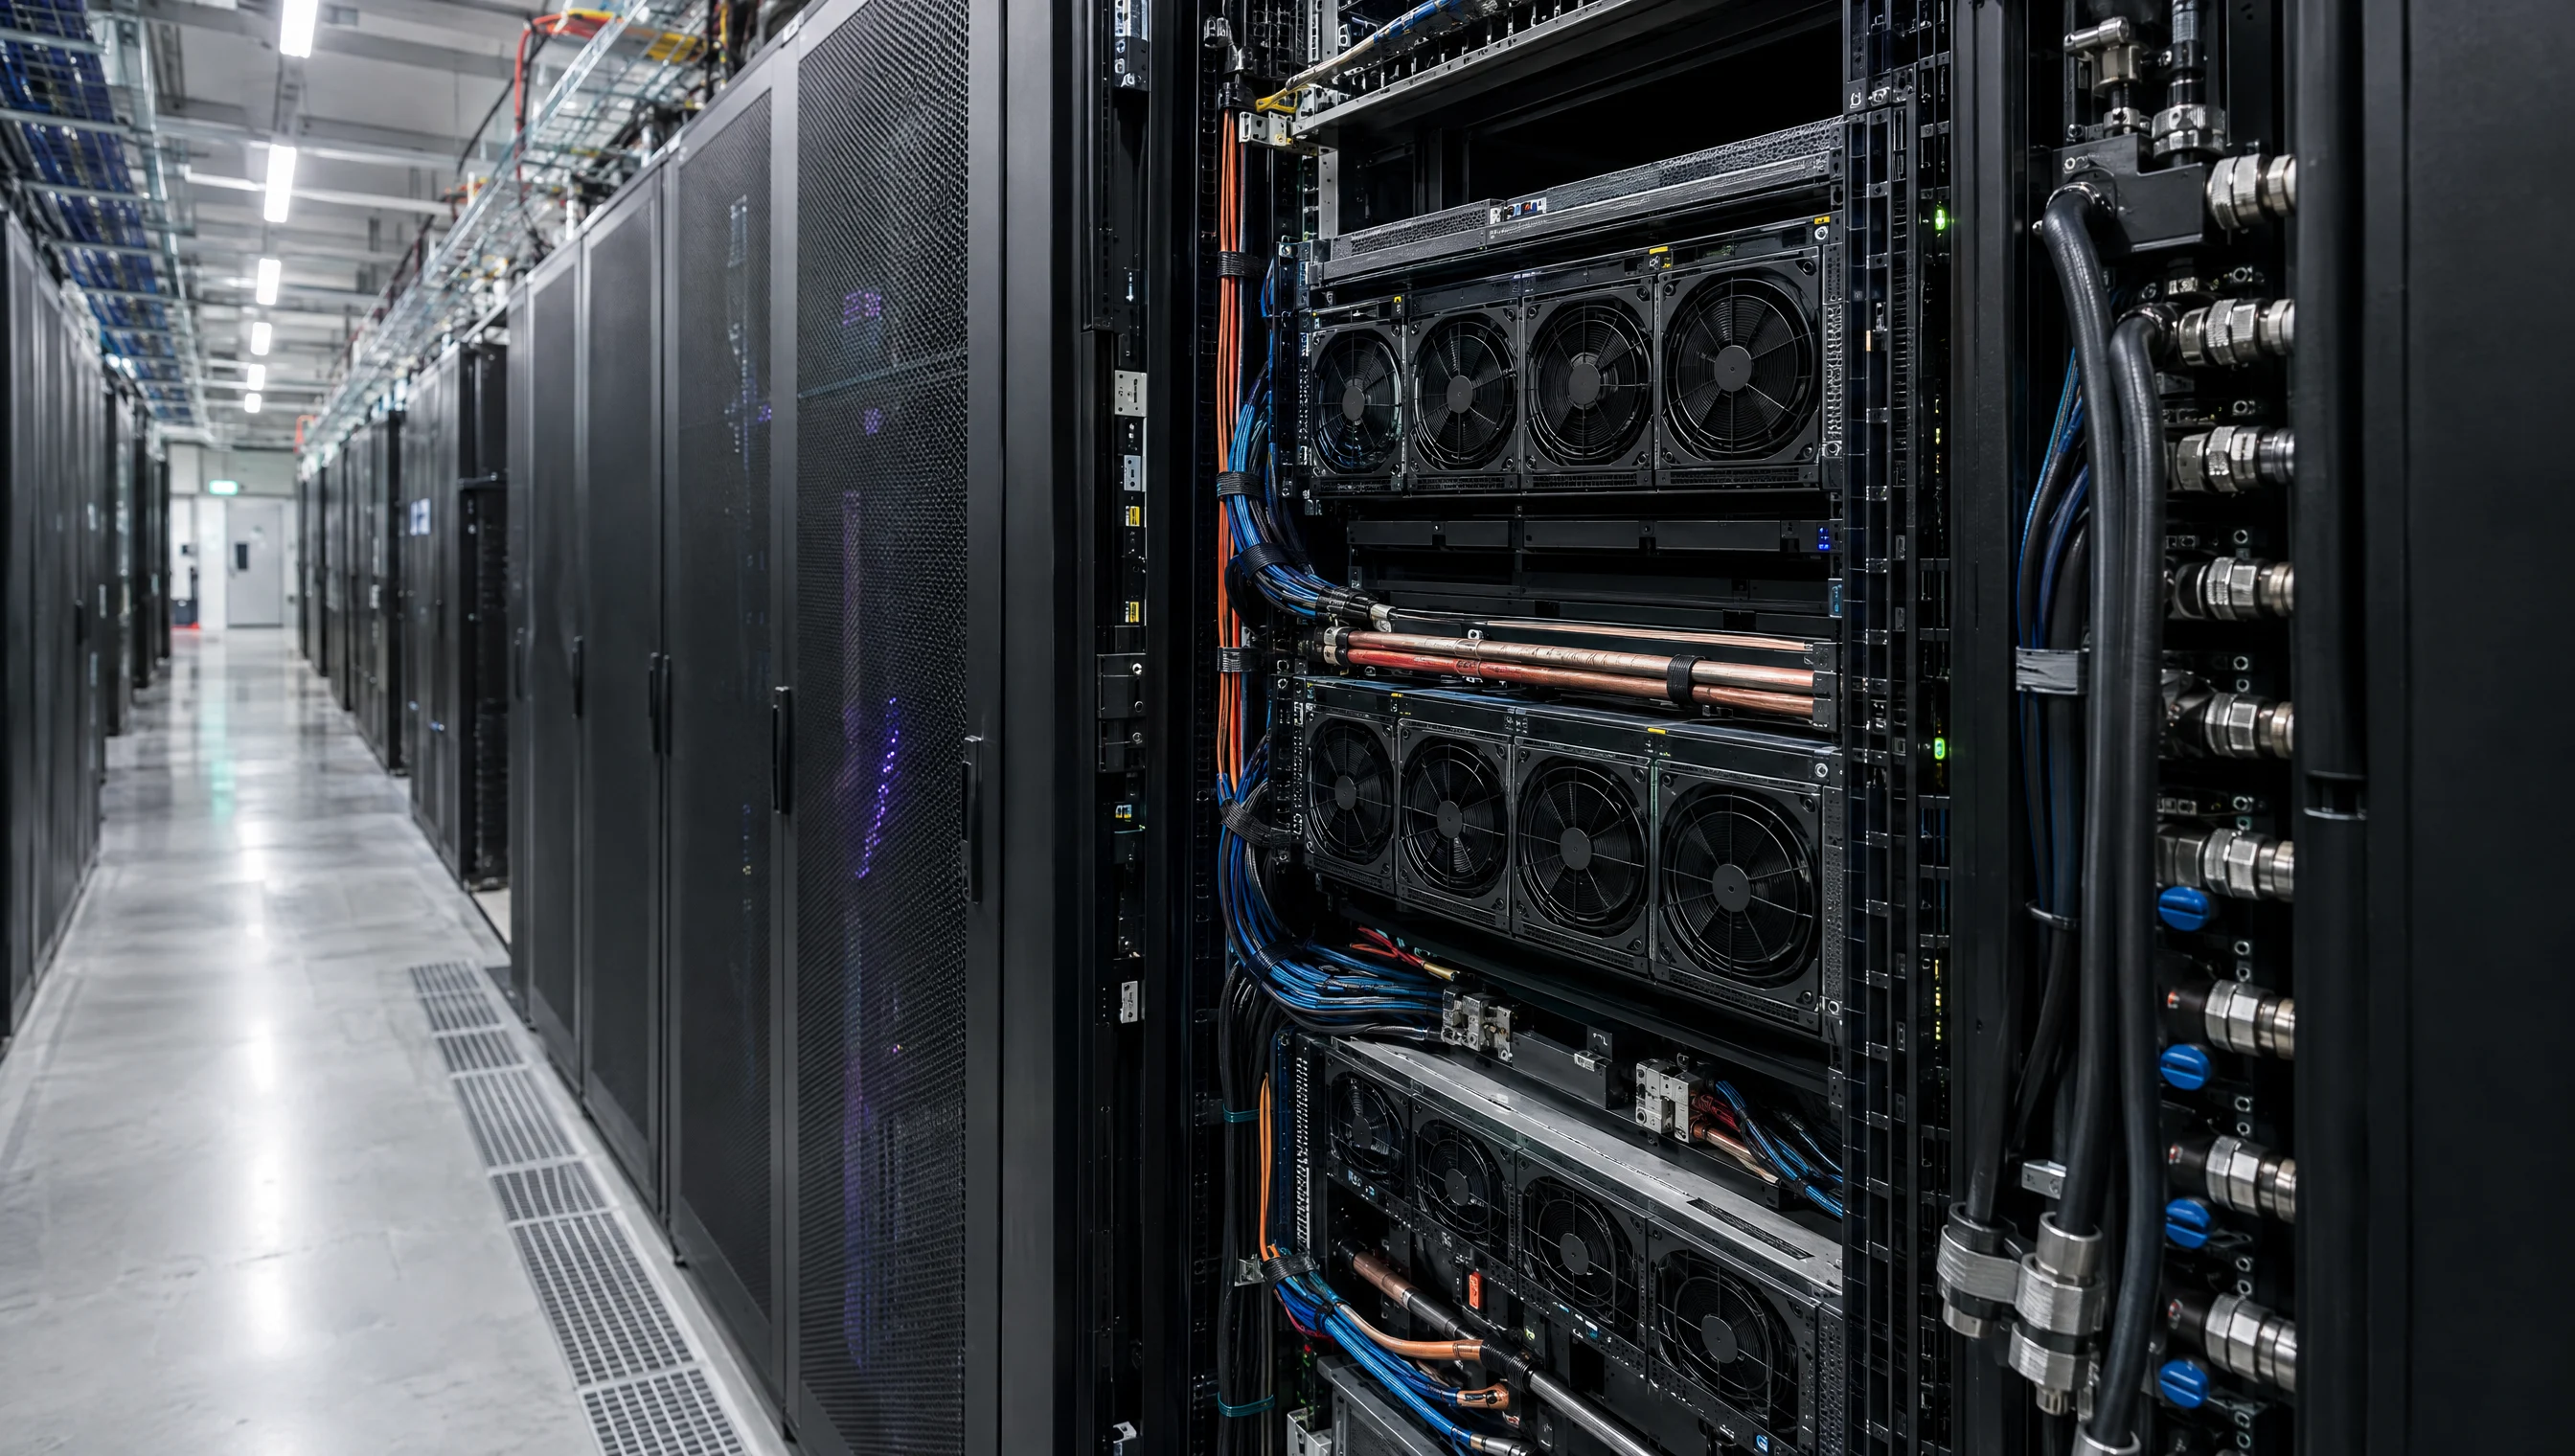
GPU COMPUTE
Compare TensorBay GPU configurations from the newest generation to the previous ones.
Find the right NVIDIA GPU
PRICING
Compare monthly and yearly reservations for GPU nodes and rack-scale systems.
Plan with published rates05Invest in your next move
Choose your reservation term, compare capacity, and plan your investment. Here, the conversation starts with open pricing.
| GPU and memory | Monthly termCapacity reserved on a monthly term | Yearly termLower hourly rate |
|---|---|---|
NVIDIAHGX B300288 GB HBM3e per GPU | Monthly from Quote monthlyUS$ 83.20/h | Yearly from Quote yearlyUS$ 58.50/h |
NVIDIAHGX B200180 GB HBM3e per GPU | Monthly from Quote monthlyUS$ 72.80/h | Yearly from Quote yearlyUS$ 50.70/h |
NVIDIAHGX H200141 GB HBM3e per GPU | Monthly from Quote monthlyUS$ 44.20/h | Yearly from Quote yearlyUS$ 31.20/h |
NVIDIAHGX H10080 GB HBM3 per GPU | Monthly from Quote monthlyUS$ 28.60/h | Yearly from Quote yearlyUS$ 19.50/h |
The hourly rate covers the complete 8-GPU node. Choose a term to request your quote.
Every detail accounted for
See what is included and explore rates for storage, data transfer, and networking.
Talk to a specialistUSD prices per 8-GPU HGX node-hour; rack-scale systems are quoted per rack. Taxes excluded. Managed Slurm and Kubernetes control planes are included. Storage and Direct Connect follow the rates above. Ask about long-term contract options.
Get my proposalPublished HGX prices are in USD per hour for a complete node with 8 GPUs, within a monthly or yearly reservation. NVL72 systems are quoted per rack. Taxes are not included.
Compare GPU memory, network requirements and your training or inference workload. The hardware section lists H100, H200, B200, B300 and full rack systems. Our team can help size a configuration based on your model, dataset and capacity requirements.
Yes. TensorBay offers dedicated NVIDIA GPU infrastructure for model training, fine-tuning and inference. You can work with Slurm, Kubernetes or SSH and configure the software environment for your workload.
Share the GPU, capacity and reservation term you need, or describe your project. Our team reviews the requirements and prepares a proposal within 48 hours, including configuration and delivery timing. Capacity and final terms are confirmed in the proposal.
08Give your idea room to grow
Bring us your challenge. Our team will help define your GPUs, capacity, and timeline. Get a proposal within 48 hours to launch your project or take it further.