
Dedicated compute in each HGX node.
WHY TENSORBAY
A GPU foundation built to move your AI forward.
Dedicated NVIDIA systems, infrastructure planned around the data path, and a team beside you from capacity planning to handover.
DETAILS THAT HELP YOUR TEAM MOVE WITH CONFIDENCE
Of system checks before cluster handover.
Node replacement service level.
InfiniBand XDR link on selected Blackwell systems.
TEAMS USING TENSORBAY
Behind the teams turning AI into business impact.
- Bank of America
- Halliburton
- BRF
- PicPay
- BMG Bank
- City of Rio de Janeiro
- CNSesi
- AICUBE
- AirCloud
BUILT AROUND THE WORK
Spend less time assembling infrastructure. More time advancing the model.
A dedicated cluster brings the pieces your workload depends on into one plan, from GPU capacity to acceptance checks and reservation terms.
- 01
DEDICATED BY DESIGN
Capacity focused on your workload
Run on dedicated GPU hardware, with node capacity reserved for your project and its training, fine-tuning, or inference needs. - 02
READINESS YOU CAN REVIEW
Start with evidence in hand
Load, memory, network, and thermal checks are completed before handover, with results available for your team to review. - 03
CLARITY BEFORE COMMITMENT
Plan against clear terms
Compare published GPU rates and reservation terms, then shape the configuration around your model and timeline.
DESIGNED FOR DATA IN MOTION
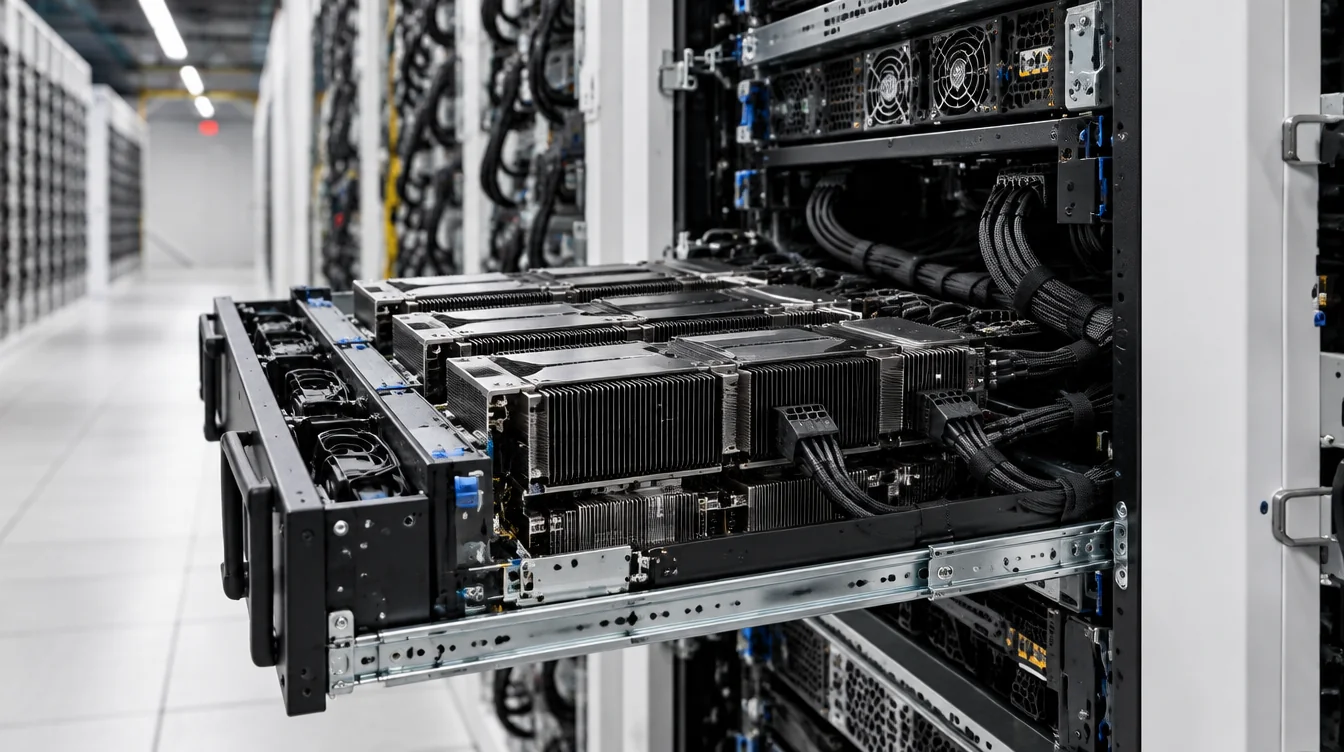
Your GPUs perform as a system.
Throughput depends on how well the network, storage, and facility keep up with compute. Plan the full path around the workload, then choose the configuration that fits.
- BLACKWELL INTERCONNECTUp to 800 Gb/s
Quantum-X800 XDR InfiniBand link on selected Blackwell configurations.
- LOCAL SCRATCHUp to 30 TB
NVMe on selected HGX nodes, depending on the configuration.
- BEFORE HANDOVER72 hours
Load, memory, network, and thermal checks, with results to review.
DIRECT EXPERT ACCESS
Work with people who know the stack.
Build the reservation plan with a team that understands GPU systems, network design, data paths, and operational readiness.
Talk with our teamFROM FIRST CONVERSATION TO FIRST RUN
A clear path from idea to infrastructure.
- 01
Scope the workload
Align the model, GPU memory, node count, data, interconnect, and launch timeline.
- 02
Plan the architecture
Choose node or rack scale, networking, storage, reservation terms, and delivery window.
- 03
Verify before handover
Review load, memory, network, and thermal checks before the cluster reaches your team.
- 04
Grow with a clear path
Discuss cluster progress and the next capacity decision with people who know the infrastructure.
TESTED BEFORE HANDOVER
Start with a cluster you can trust.
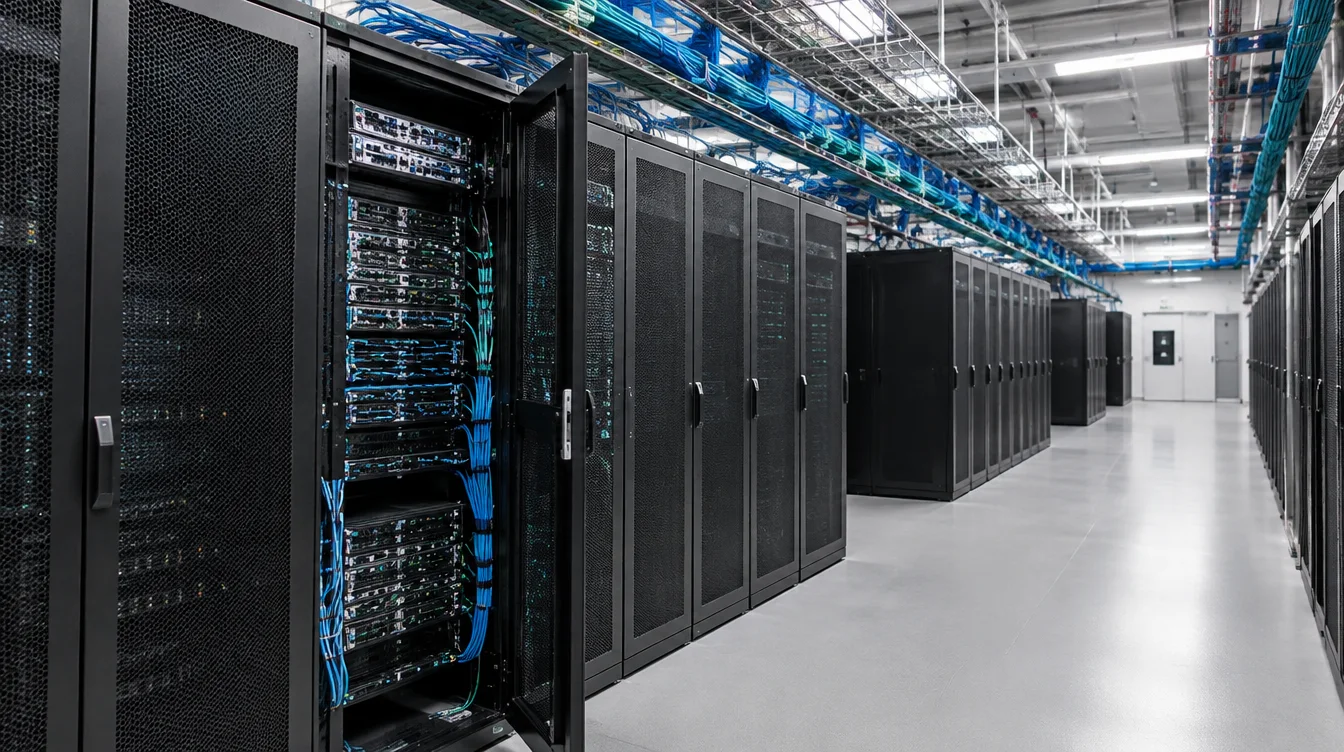
Every cluster goes through 72 hours of load, memory, network, and thermal tests. Your team reviews the results before approving delivery.
72h
ACCEPTANCE TESTING
Load · memory · network · thermal checks
AI WORKLOADS
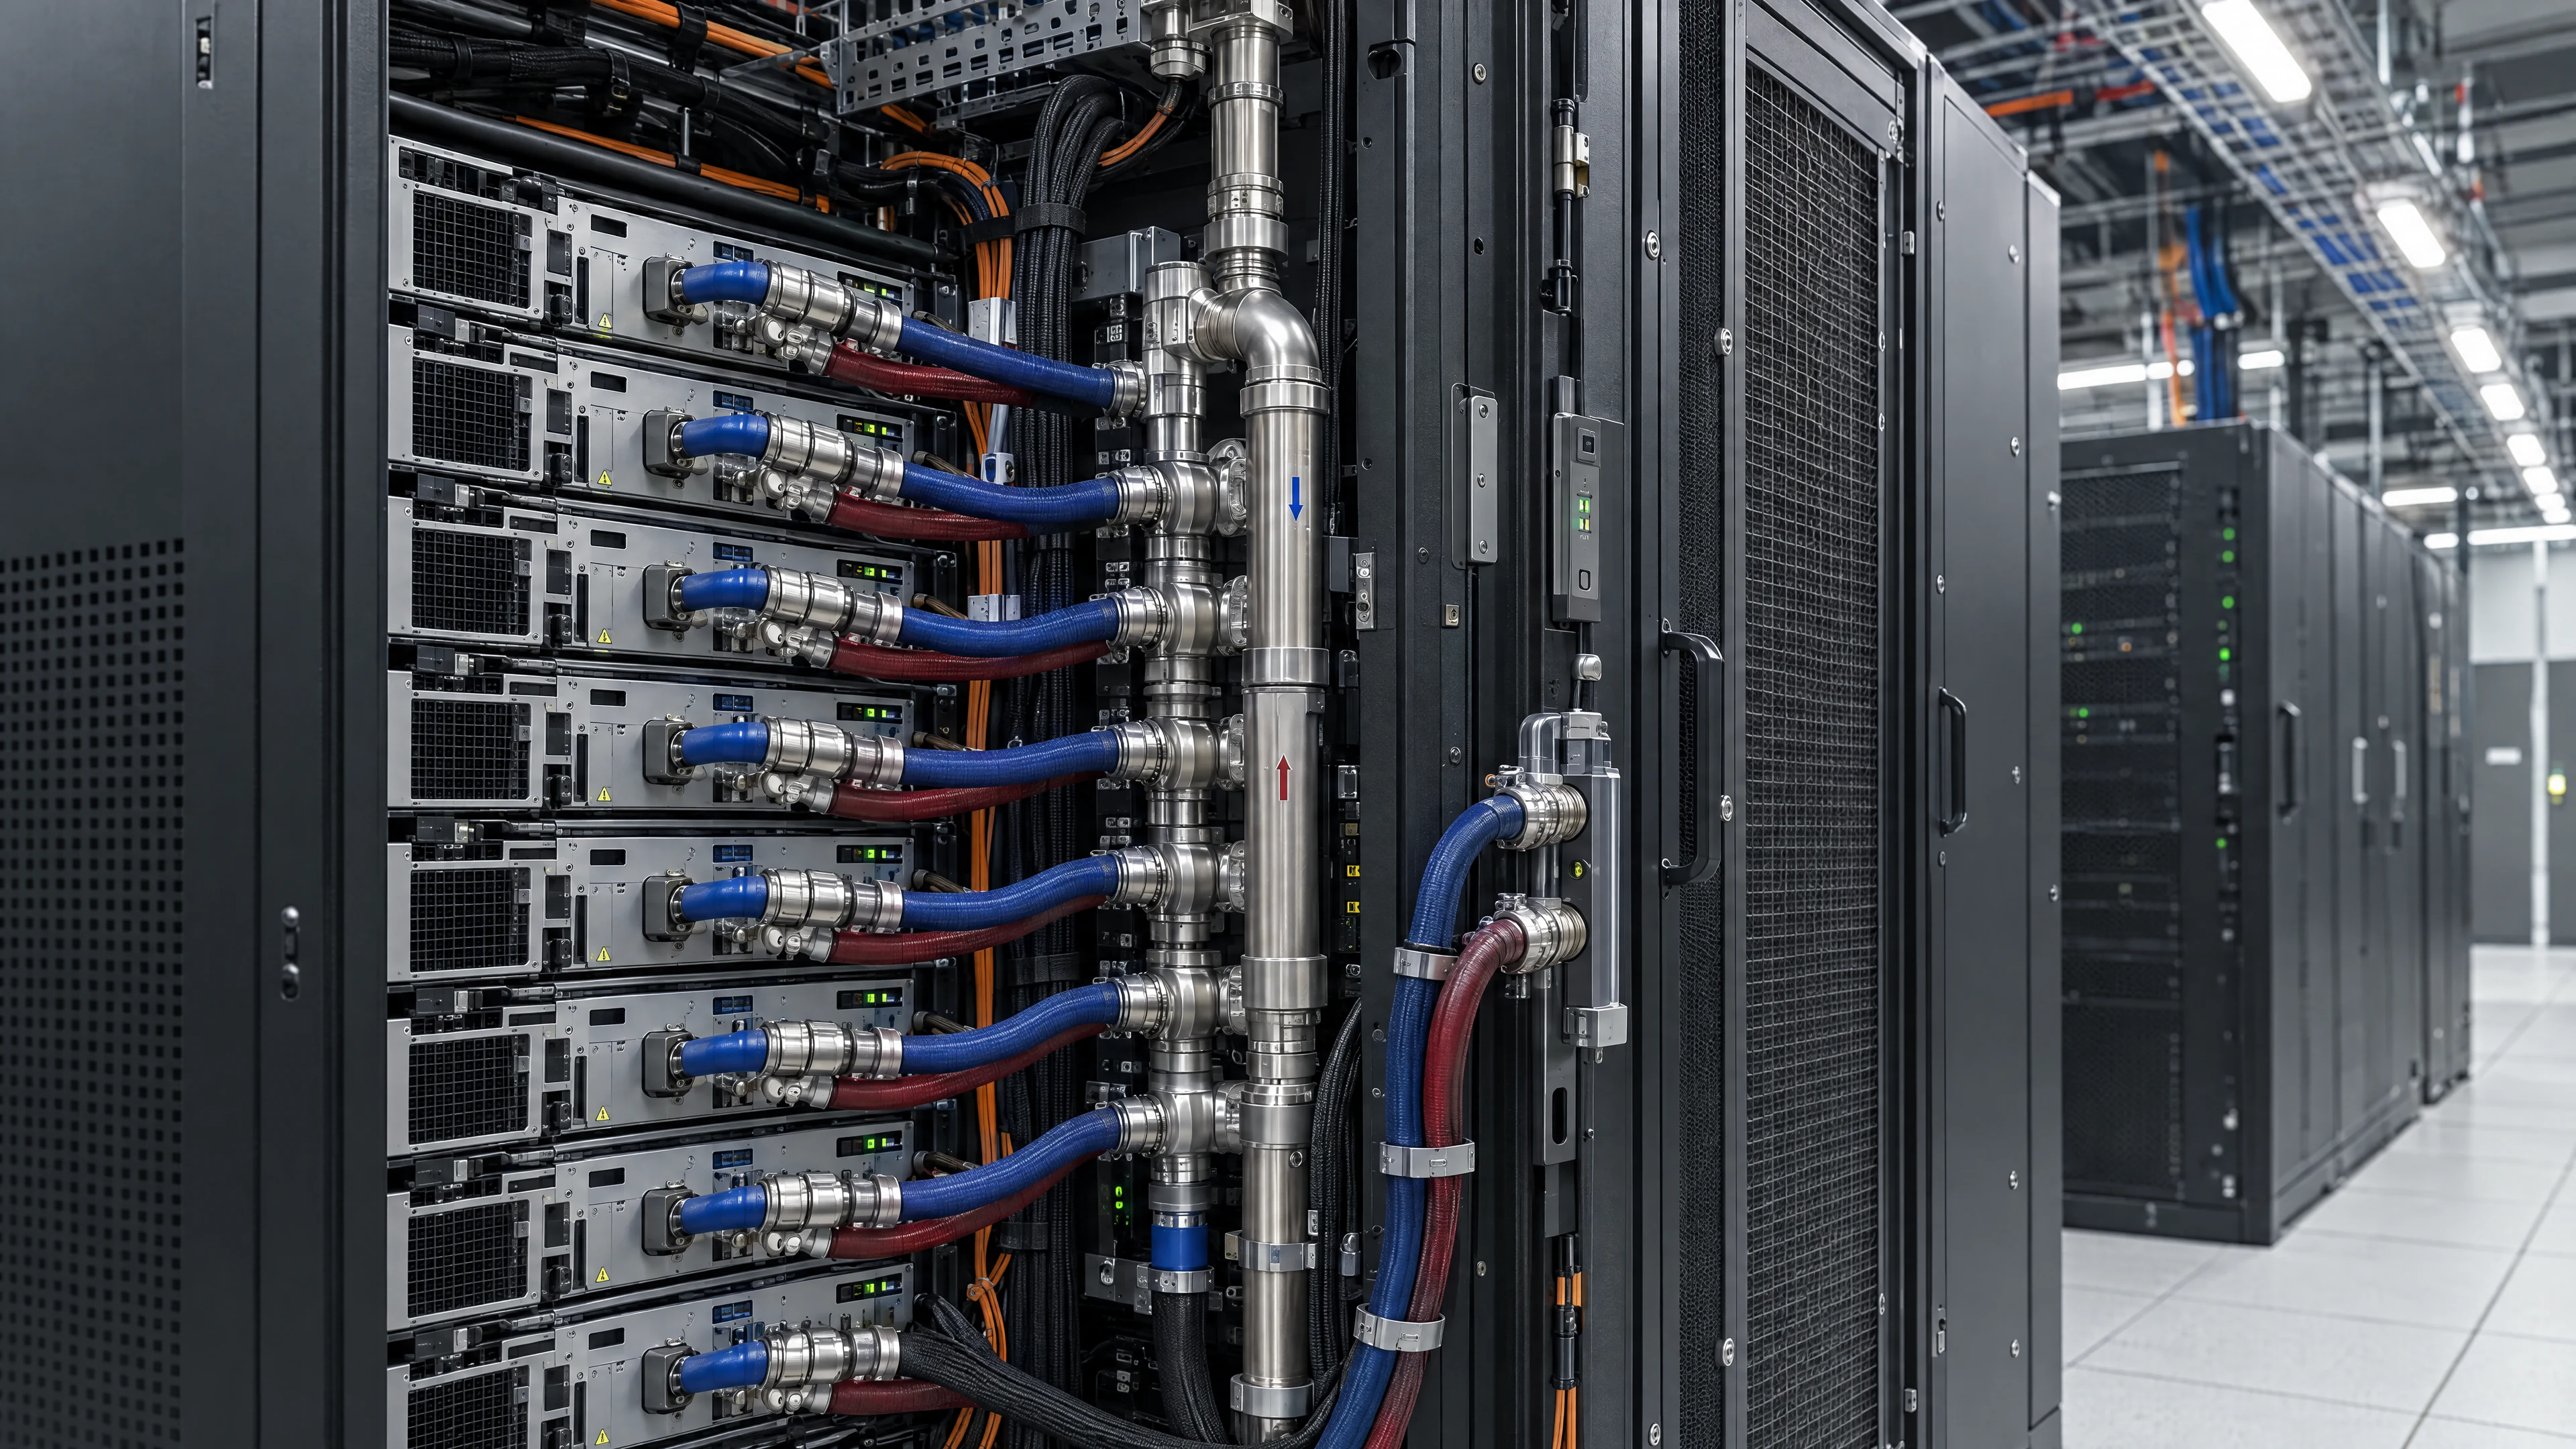
- TENSORBAY AIFACTORYModel trainingDedicated GPUs and high-speed networking for long training runs.
- TENSORBAY AIFACTORYFine-tuning & research8-GPU nodes for adapting models and iterating on experiments.
- TENSORBAY AIFACTORYProduction inferenceMemory-rich systems for serving models on dedicated infrastructure.
07Confidence to move forward
Your innovation deserves a secure foundation.
Bring projects to production with dedicated hardware, physical isolation, and access controls. Security is part of the infrastructure, from the first node.
SOC 2 Type II
Scope: bare-metal compute, fabric, and managed storage
ISO 27001:2022
Certified — all datacenter sites
HIPAA
BAA available on dedicated clusters
GDPR
EU region with in-country data residency
- Hardware, networking, and storage physically dedicated to your operation
- Encryption at rest and secure data erasure when hardware is released
- Certified destruction of retired storage media
- Enterprise sign-in, hardware-key authentication, and immutable audit logs
- Review scope and reports at trust.tensorbay.com
Is GPU pricing per GPU or per node?
Published HGX prices are in USD per hour for a complete node with 8 GPUs, within a monthly or yearly reservation. NVL72 systems are quoted per rack. Taxes are not included.
Which NVIDIA GPU should I choose for my AI project?
Compare GPU memory, network requirements and your training or inference workload. The hardware section lists H100, H200, B200, B300 and full rack systems. Our team can help size a configuration based on your model, dataset and capacity requirements.
Can I use a dedicated cluster for training, fine-tuning and inference?
Yes. TensorBay offers dedicated NVIDIA GPU infrastructure for model training, fine-tuning and inference. You can work with Slurm, Kubernetes or SSH and configure the software environment for your workload.
What happens after I request a quote?
Share the GPU, capacity and reservation term you need, or describe your project. Our team reviews the requirements and prepares a proposal within 48 hours, including configuration and delivery timing. Capacity and final terms are confirmed in the proposal.
08Give your idea room to grow
Make your next AI move with a clear plan.
Bring us your model, capacity goals, and timeline. We will help you map a GPU configuration and the steps to get it ready.
- A configuration built around your project
- A proposal with a delivery timeline
- Acceptance testing before you start